What's new
in Worca.
Since 1.3.0 — runs that start while you sleep and follow one another, your own code as workflow cards, Copilot and local models, a team policy kept in git, and a screen that starts simple.
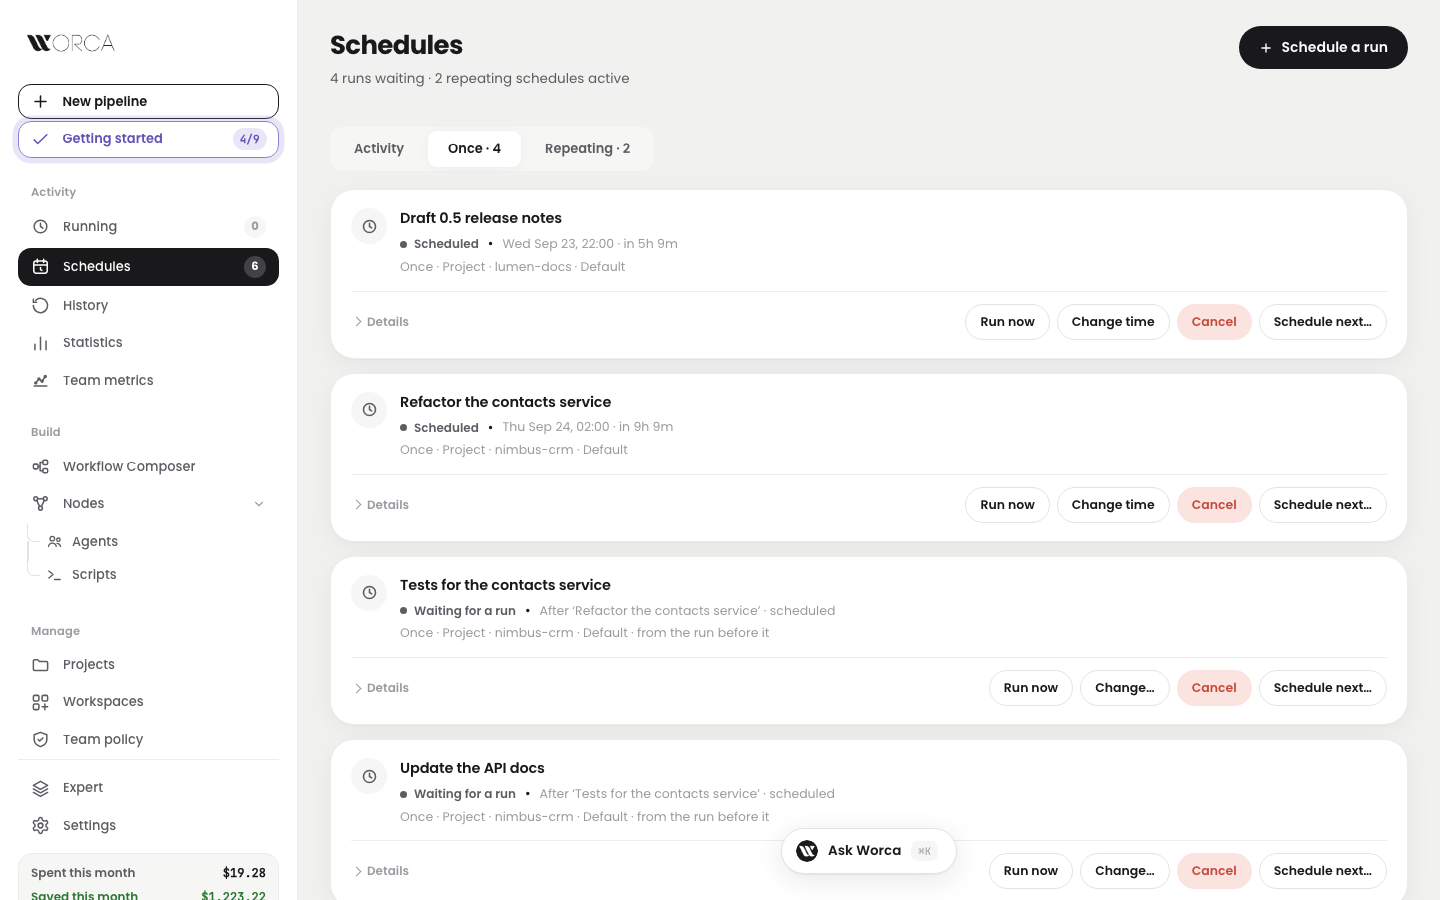
Schedule runs, once or on repeat.
Want the big refactor to run overnight, not while you wait?
Now pick a time instead of pressing Start: once, every weekday, or on a rule of your own. A run can also wait for another run and start on the branch it left, so refactor, tests and docs run one after another.
If a run fails, the next one does not start, unless you tell it to.
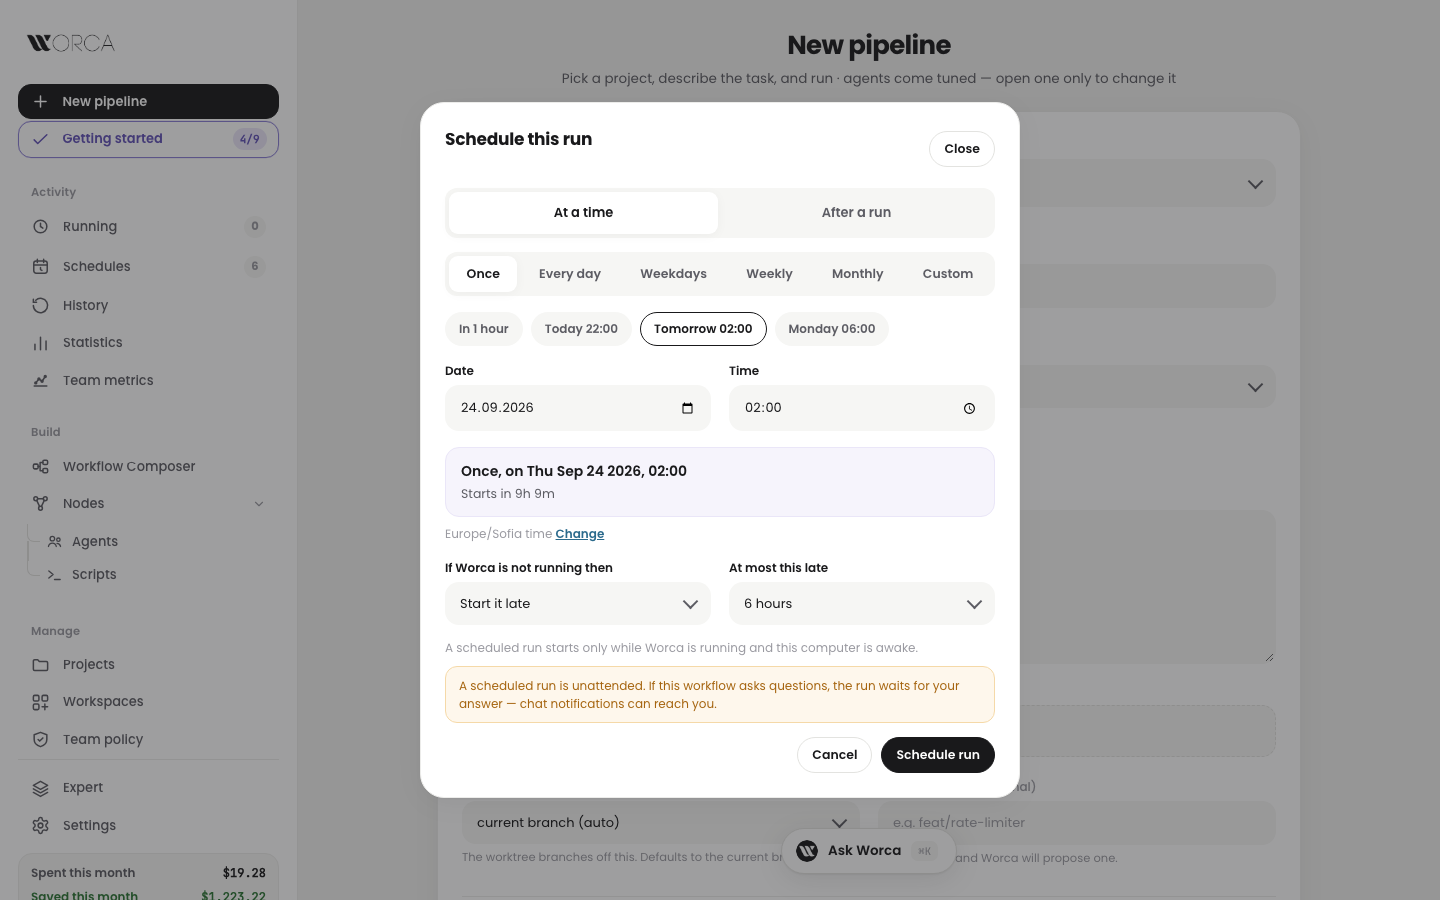
The schedule sheet: once or on repeat, quick picks, and when it will start.
Workflow cards that run your code.
Does a test gate really need a model call?
Now a script card runs your own Node, Python or shell program inside a workflow. It has the same wires and pass/fail routing as an agent, costs no tokens, and gives the same answer every time. Try it on the test bench before it goes into a run.
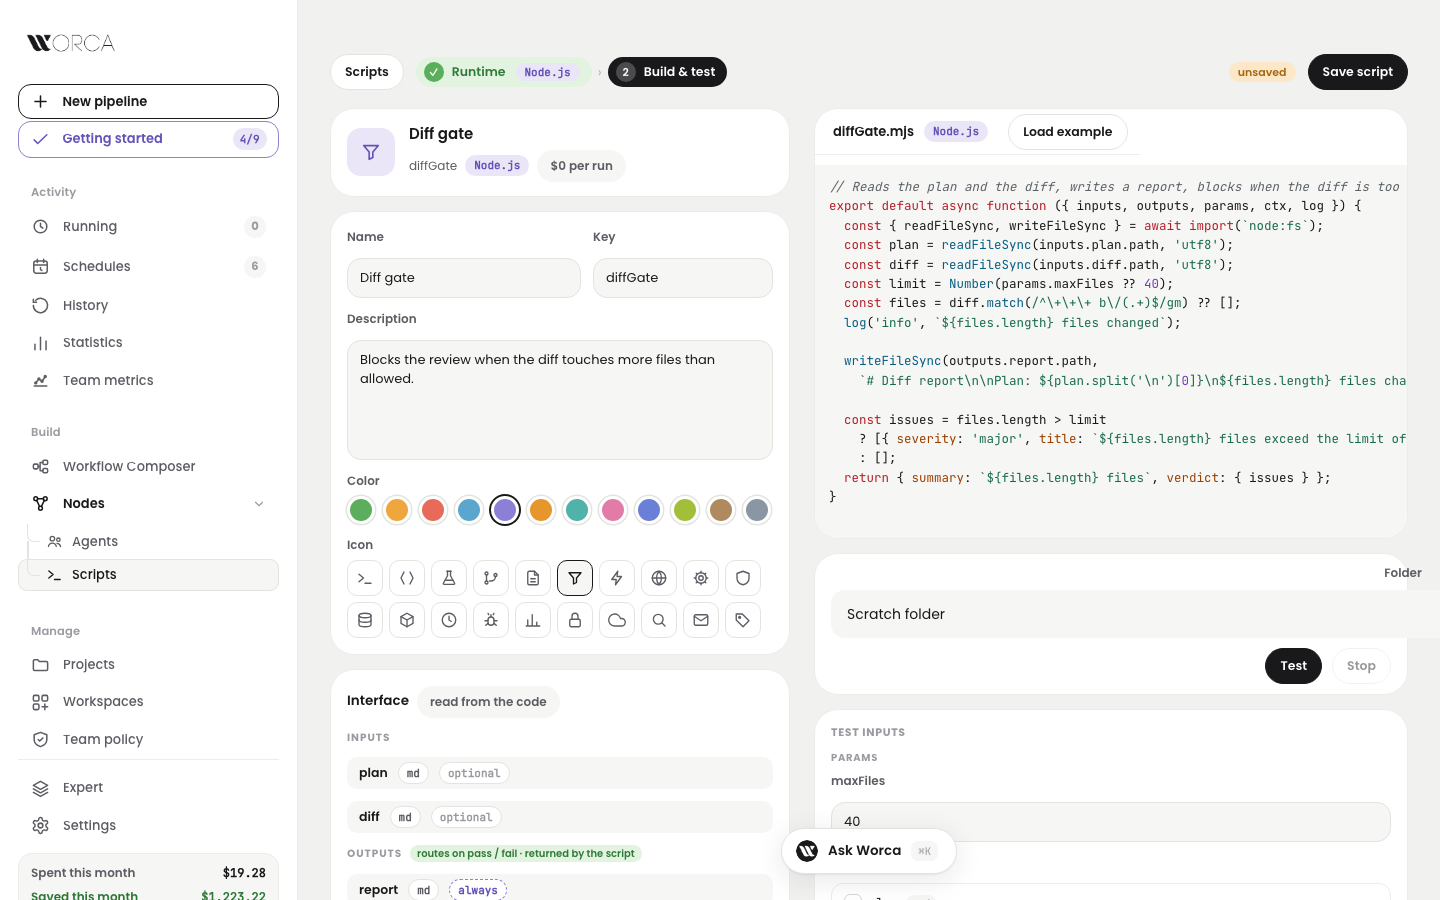
A new script: the inputs and outputs are read from the code as you type.
The same routing as an agent card, without a model call.
Run pipelines on Copilot or local models.
Paying for Copilot, or running Ollama on your desk, while Worca only talked to Anthropic?
Now Worca has a bridge built in. Sign in to GitHub Copilot or point it at a server on your machine, import the models it serves, and pick them anywhere you pick a model.
Worca asks the server, so a prompt never outgrows the model.
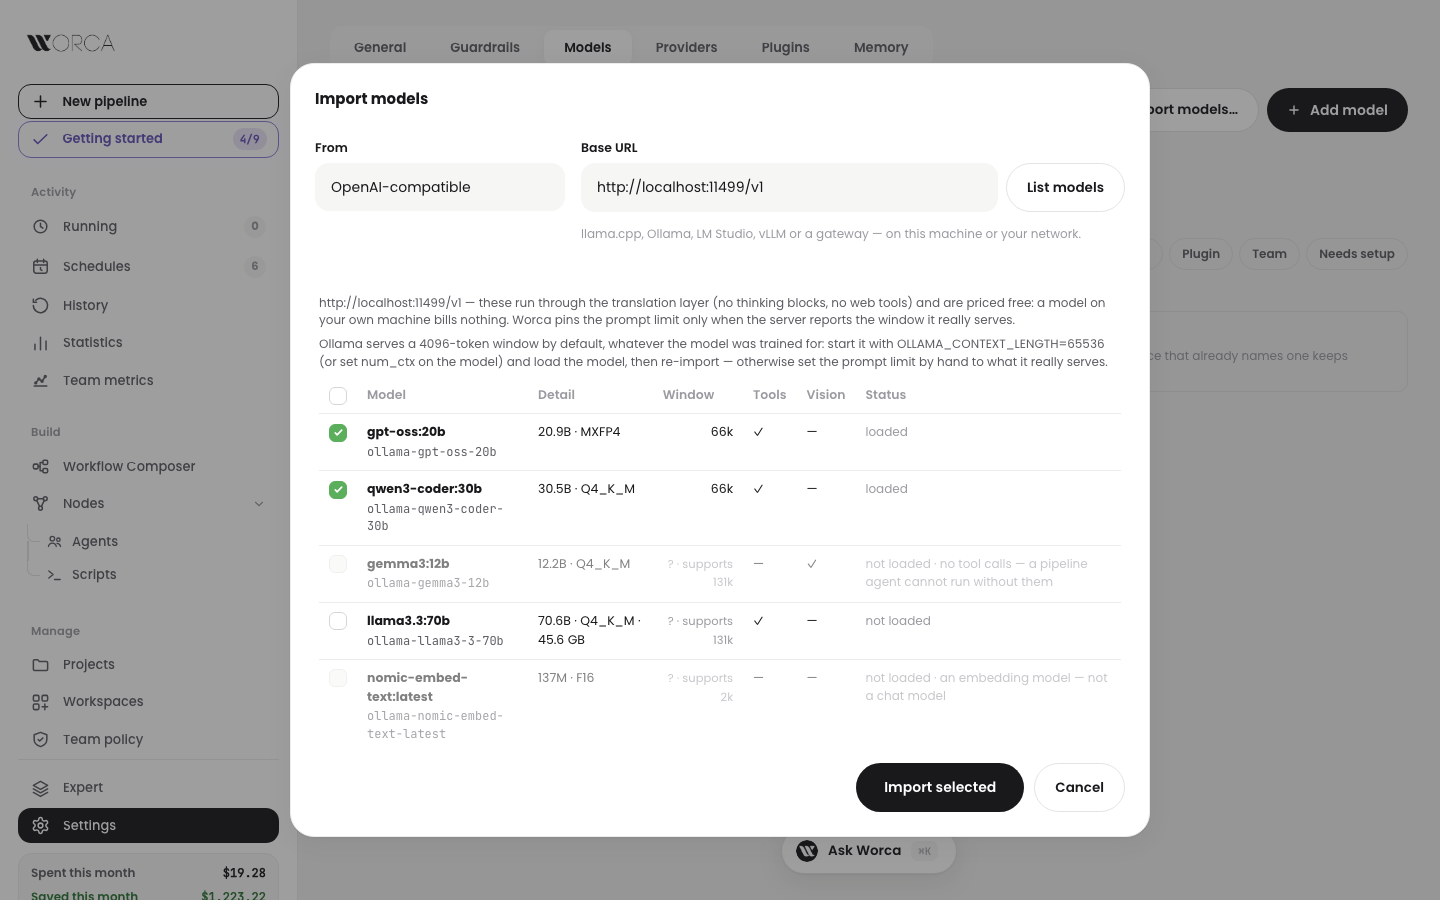
Import models: what a local Ollama serves, and which ones can run a pipeline.
One team policy, kept in git.
Does everyone on the team run with different caps, models and plugins?
Now a maintainer publishes a team policy to a branch in the project's repository, and every teammate's Worca reads it: cost caps, allowed models, required plugins and guardrails. Nothing is blocked. Go past a cap with a reason and the team sees it.
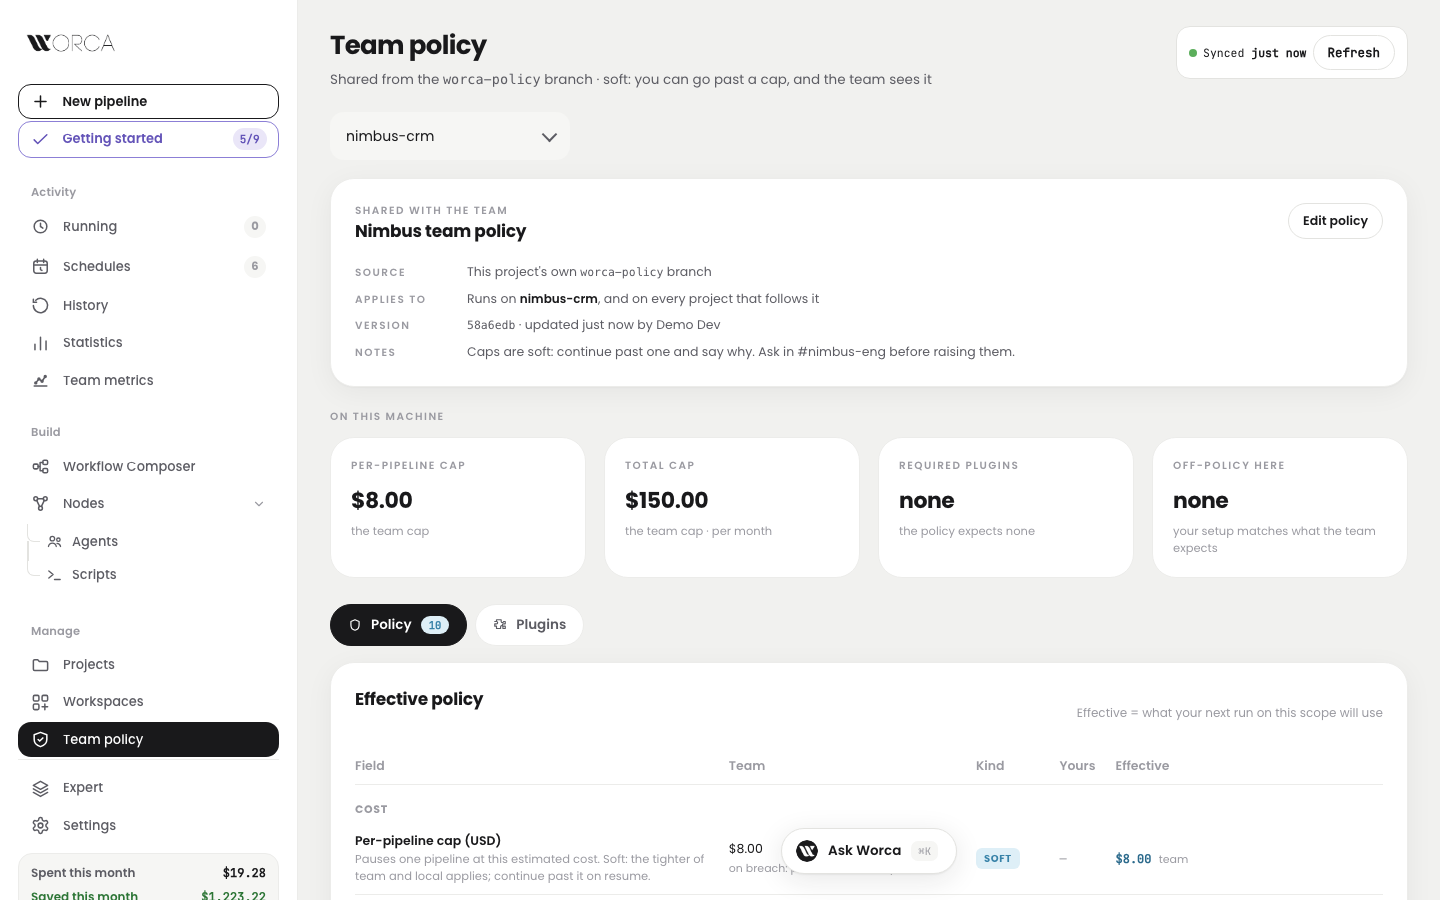
The Team policy page: what the team published and what your next run will use.
- 1The run pauses at the cap
- 2You continue and say why
- 3The team sees it in Team metrics
Simple, Advanced or Expert: you choose.
Too many buttons on your first day?
Now you pick how much of Worca is on screen. Simple shows what a run needs, Advanced adds control and review, and Expert shows everything. Nothing is switched off, only tidied away, and you can change it any time.
Links still open at any mode, with an offer to switch.
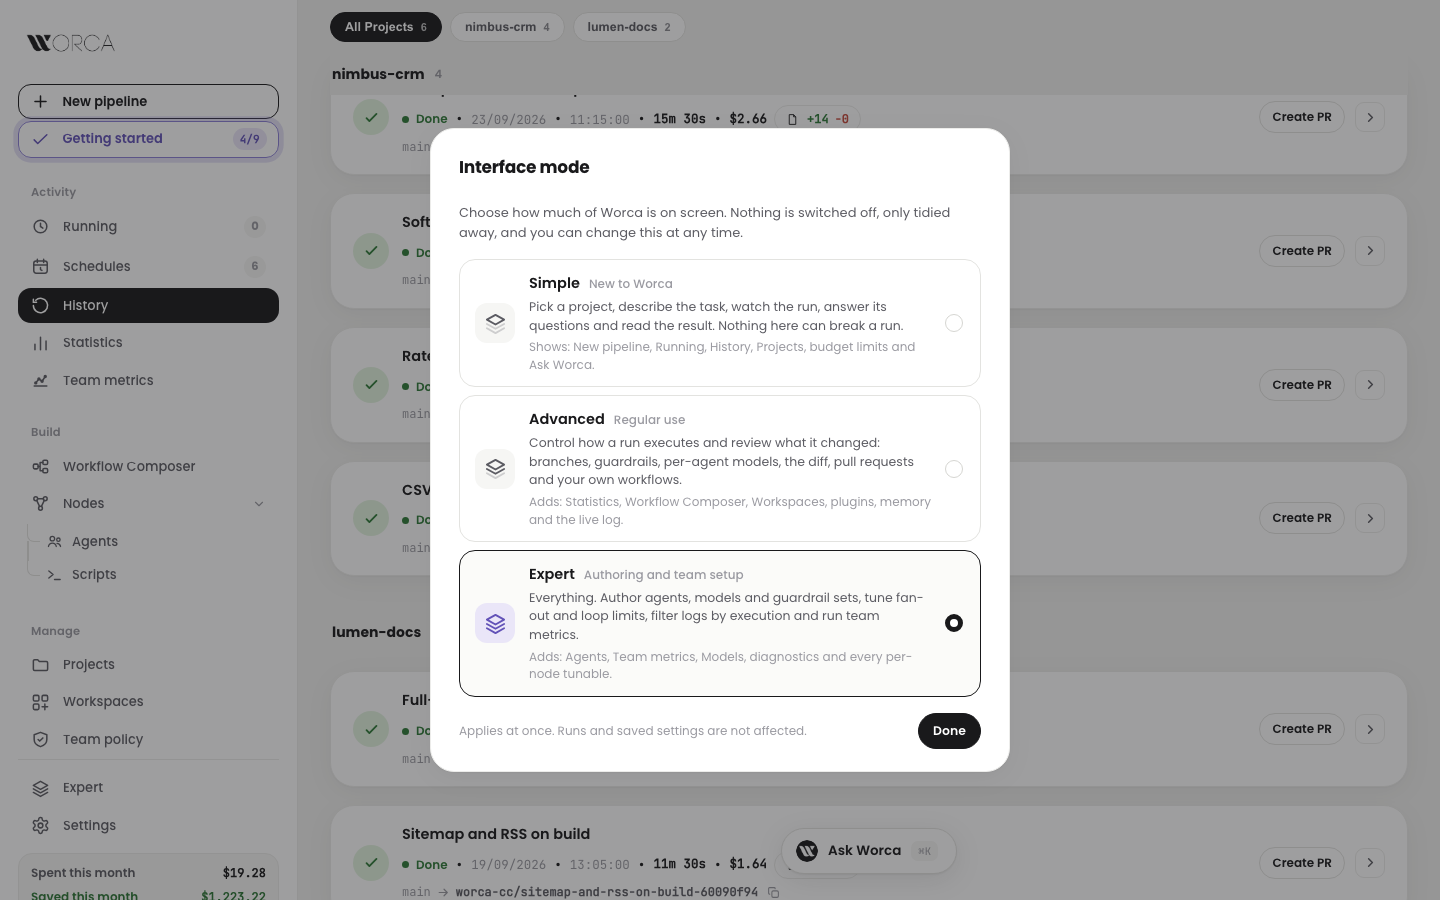
The interface mode dialog, one click from the sidebar.
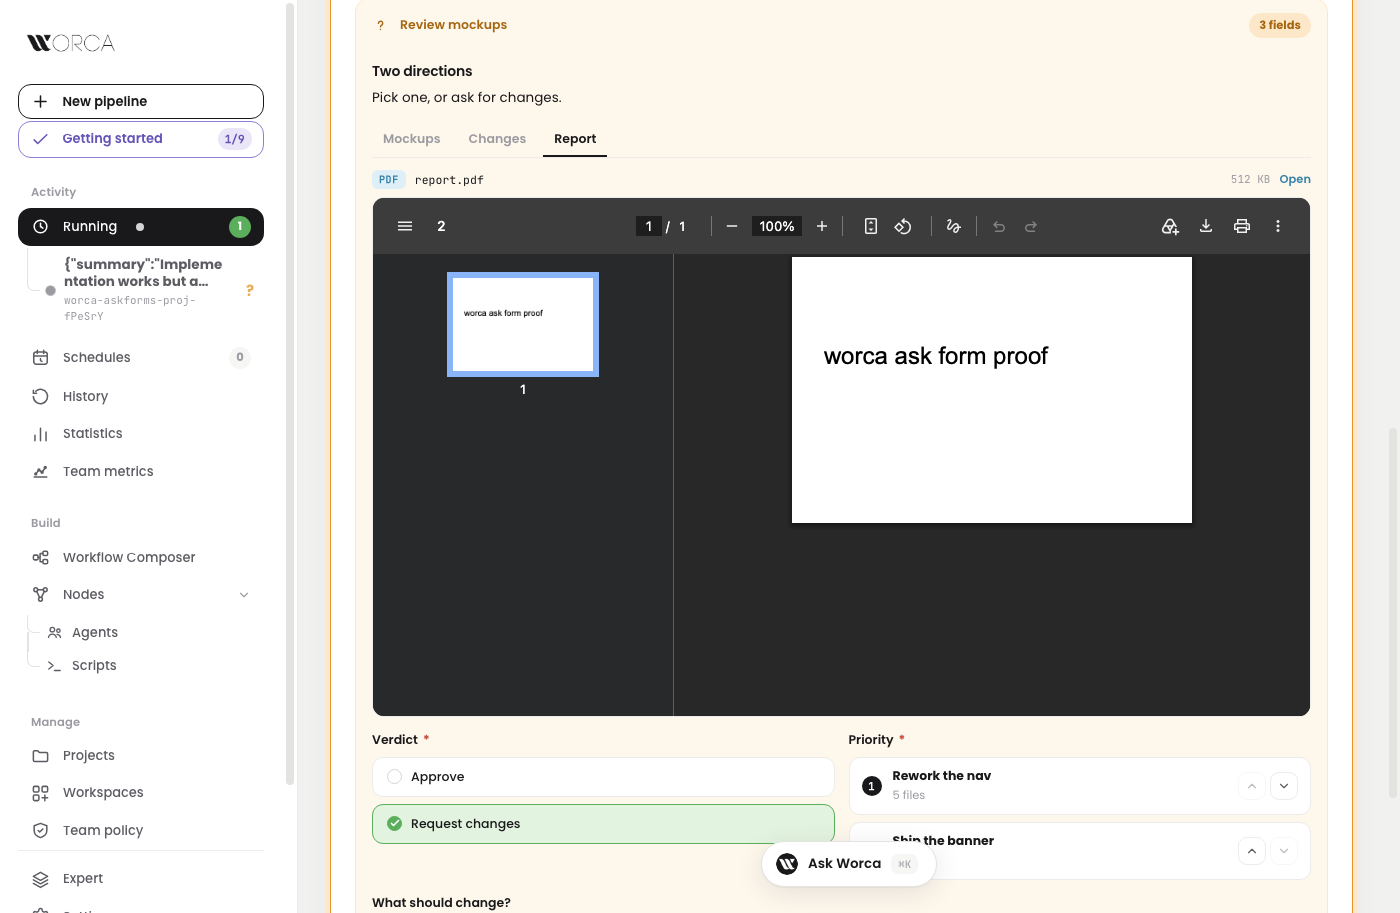
Agents ask with forms, not just text.
An agent wants you to judge six findings in one free-text box?
Now an agent can bring the form its question needs: pick one, rank a list, keep or waive each finding, compare two images. Worca checks your answer before the agent sees it. The built-in code reviewer already asks this way.
the form, with live checks/answer *a1 verdict=changes | priority=nav,bannerasks one field at a time, then re-asks what was wrongEvery surface gets the same fields, so no answer is ever lost.
See the hours each run saved.
Is Worca worth what it costs?
Now every step of a run is credited with the hours a developer would have needed for what it produced. Statistics and the sidebar show Saved next to Spent: those hours at your hourly rate, minus what the run cost.
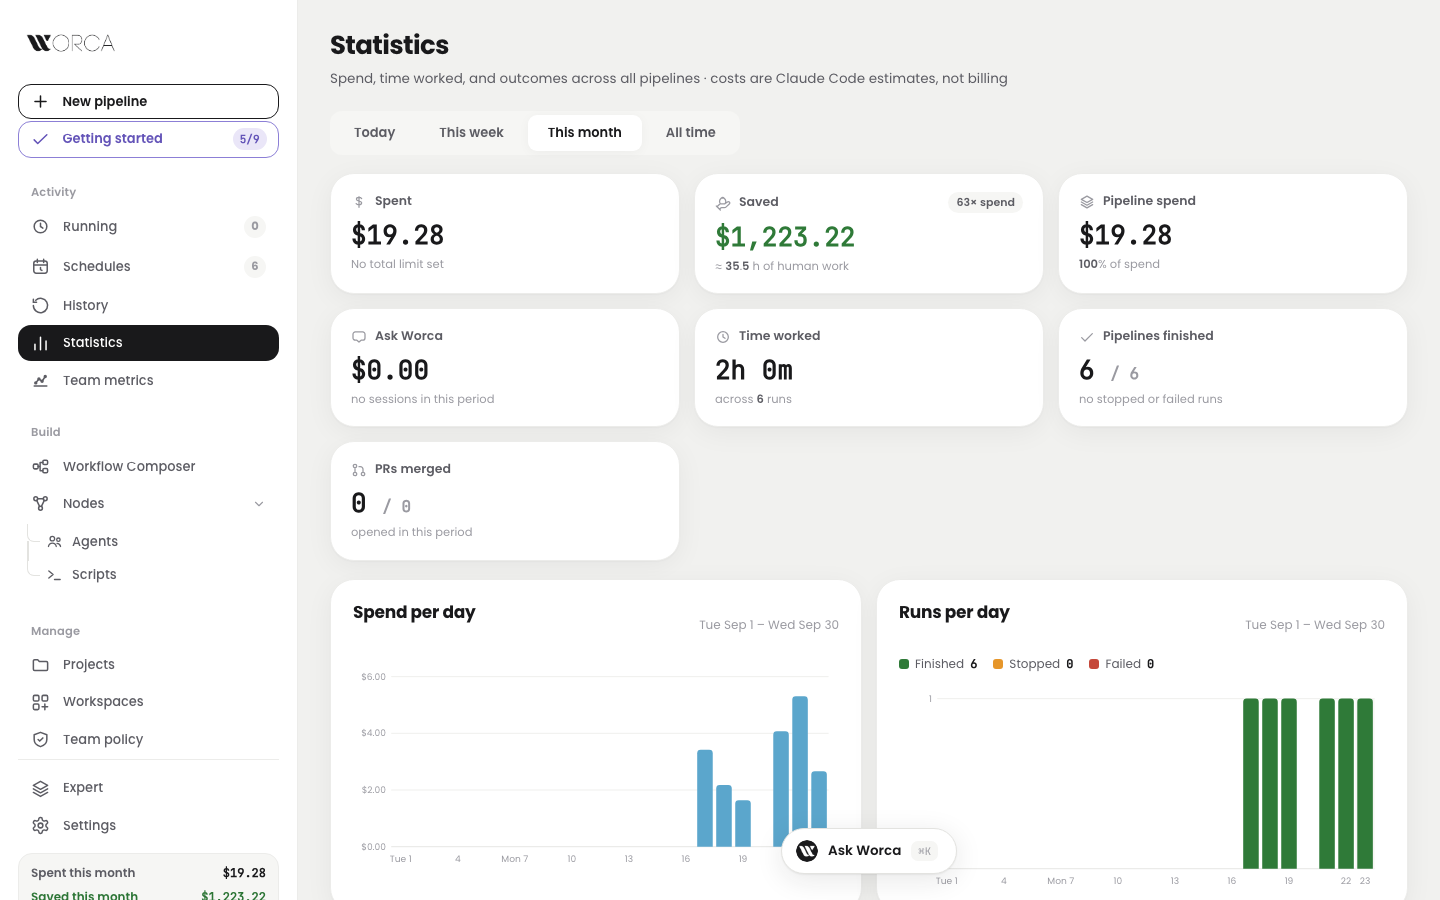
Statistics: Saved beside Spent, with the hours of human work behind it.
- 1Plan and review0.8 h
- 2Code and files changed3.1 h
- 3Code review0.6 h
A failed run that produced nothing counts against you.
Shipped, tested, verified live.